Oct 14, 2026
The loudest part of the waveform had zero words in the transcript.
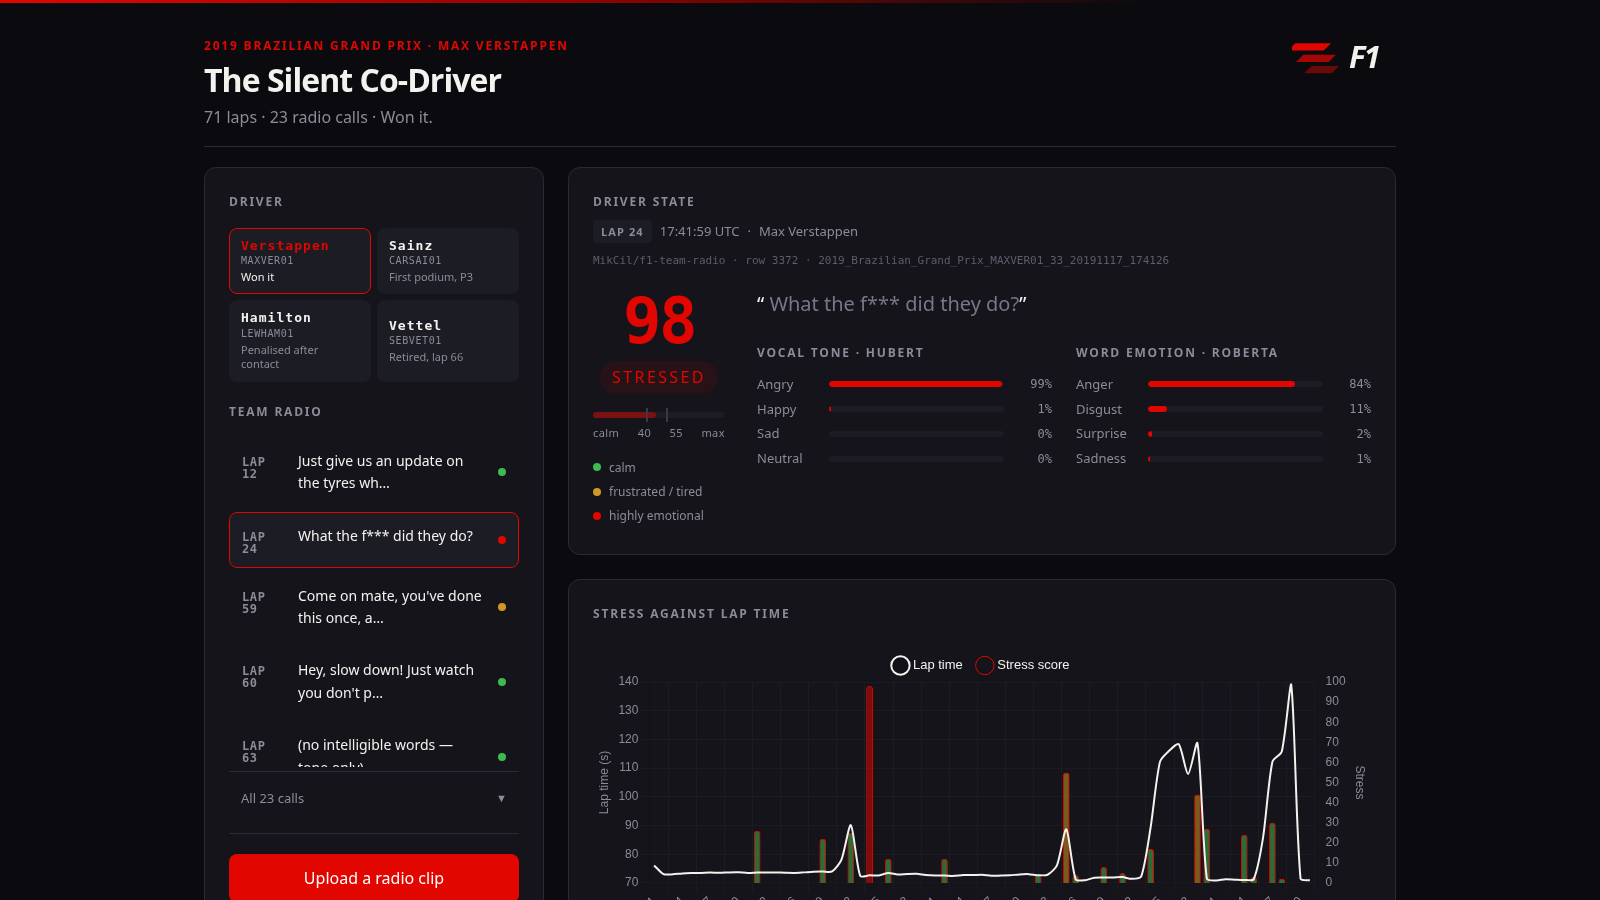
That was the only sign Whisper was dropping someone.
We built The Silent Co-Driver in a day for AI Race Month, two of us, and took 3rd: it listens to Formula 1 team radio, transcribes every call with faster-whisper, and scores how stressed the driver sounds from 0 to 100.
Except Whisper silently dropped whichever speaker talked first.
On team radio the driver asks and the engineer answers. So we kept the engineer's calm reply and threw away the driver's question, on a project whose entire job is reading the driver's voice.
Wrong person. Every score.
No error, no warning, and transcripts that looked fine.
The fix was one argument. vad_filter=True runs voice activity detection first and hands Whisper only the speech segments, instead of letting the decoder decide on its own what counts as speech.
It cost us something. VAD trims some word starts.
We kept it, because a garbled phrase is a far smaller failure than a missing speaker.
Rule for next time: when a model's output looks fine, check it against the raw input once.
What's the quietest failure a model has ever given you?
#whisper #python
Discuss on LinkedIn → Newer: Discord caps a bot at 100 top-level slash commands. → Older: My Discord bot's memory climbed every day, and the JavaScript heap never moved. →